The Limitations of Traditional SRE
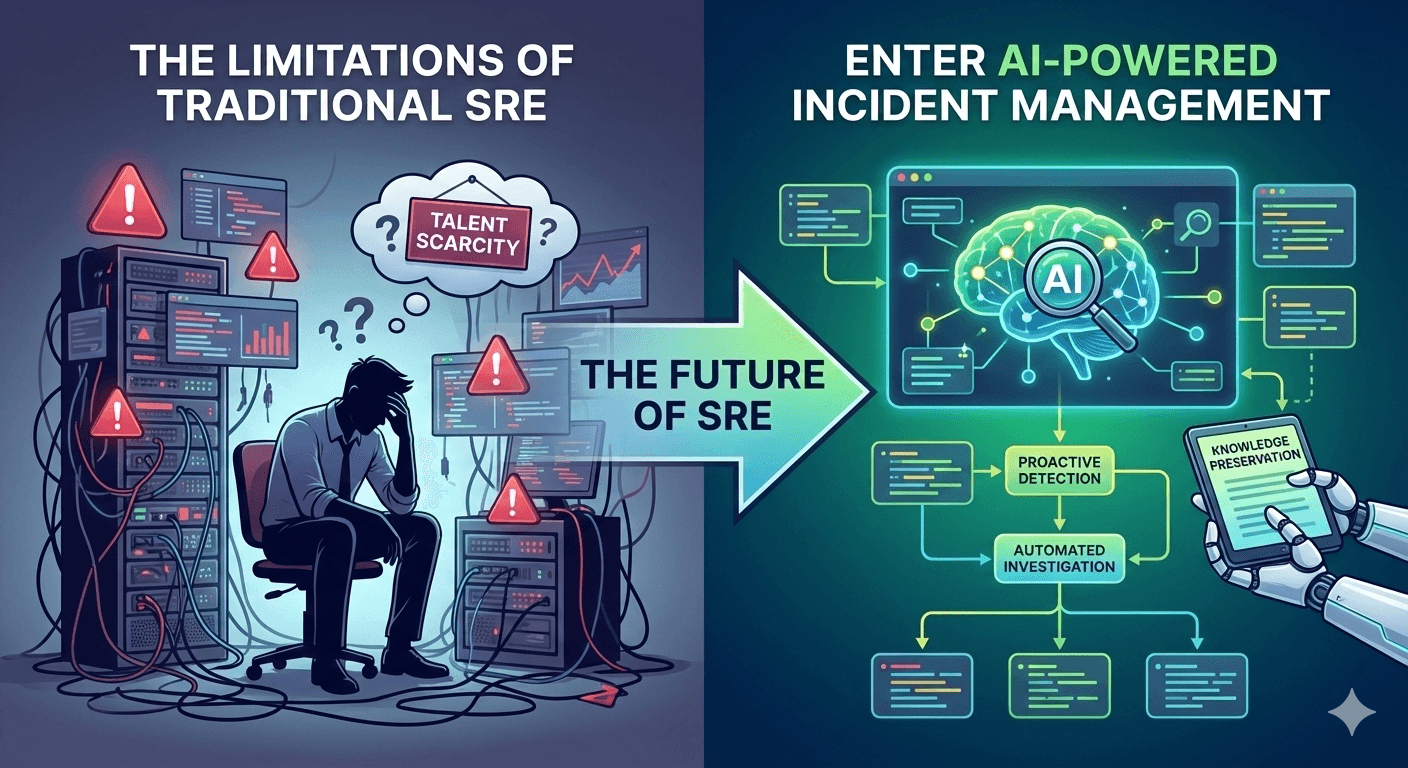
Traditional SRE practices have served us well, but they face significant challenges:
- Scale complexity Modern systems have too many components for humans to comprehend fully
- Knowledge silos Critical information is scattered across teams and tools
- Alert overload Engineers face an increasing barrage of notifications
- Talent scarcity Experienced SREs are difficult to find and retain
Enter AI-Powered Incident Management
Artificial intelligence is uniquely suited to address these challenges. To understand what AI SRE addresses at a fundamental level, from cognitive bias to knowledge preservation, start with the core concepts. Here's how:
1. Comprehensive System Understanding
AI systems can ingest and process:
- Architecture diagrams and documentation
- Historical incidents and their resolutions
- Code repositories and deployment patterns
- Real-time telemetry from thousands of services
- Chat logs from incident response channels
This creates a holistic understanding of the system that no single human could match.
2. Proactive Issue Detection
By analyzing patterns across various data sources, AI can:
- Identify anomalies before they trigger traditional alerts
- Recognize emerging patterns that precede known failure modes
- Correlate seemingly unrelated metrics to predict issues
- Detect subtle degradations invisible to threshold-based monitoring
3. Automated Investigation
When issues occur, AI assistants can:
- Gather all relevant context automatically
- Run diagnostic playbooks without human intervention
- Identify probable root causes based on historical patterns
- Suggest potential solutions with confidence ratings
- Create clear summaries for human responders
4. Knowledge Preservation and Application
AI systems excel at:
- Capturing and organizing institutional knowledge
- Applying past learnings to new situations
- Suggesting relevant historical incidents during similar outages
- Creating and maintaining documentation
Real-World Impact
Organizations implementing AI-powered incident management report.
- 70% reduction in MTTR (Mean Time To Resolution)
- 65% decrease in incident frequency
- 85% improvement in on-call quality of life
- Significant reduction in "repeat incidents"
Perhaps most importantly, these systems free SREs from routine firefighting to focus on proactive reliability improvements. Understanding accuracy and reliability standards is crucial, even impressive metrics don't tell the full story of achieving elite reliability.
The Human+AI Partnership
The future isn't about replacing SREs with AI, but creating a powerful partnership:
- AI handles routine investigations, context gathering, and pattern recognition
- Humans provide nuanced judgment, stakeholder communication, and creative problem-solving
This partnership elevates the SRE role from reactive firefighting to strategic reliability architecture.
Getting Started
How can your organization prepare for this AI-powered future?
- Consolidate your observability data Break down data silos
- Document your systems rigorously Feed the AI with quality information
- Capture incident knowledge Create structured post-mortems
- Experiment with AI assistants Start with focused use cases. Review the AI SRE tools available to find the right fit for your organization's maturity level and needs.
- Develop AI literacy in your team Build skills for the future
The organizations that embrace these changes today will have a significant competitive advantage in system reliability tomorrow.
Conclusion
AI-powered incident management isn't just a futuristic concept it's already transforming how leading organizations handle reliability. By combining the pattern-recognition and data-processing capabilities of AI with the nuanced judgment of experienced SREs, we can create reliability practices that were previously impossible.
The future of SRE isn't just about better tools, it's about a fundamentally new approach to managing complex systems.